 clovercoder
A 0.8B model that just decides
A 0.8B model whose only job is picking from a list.
firelex/jeff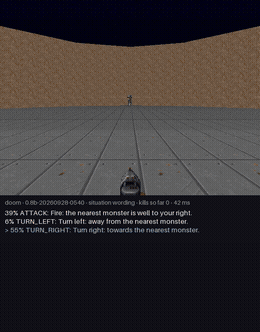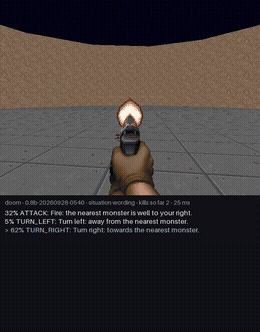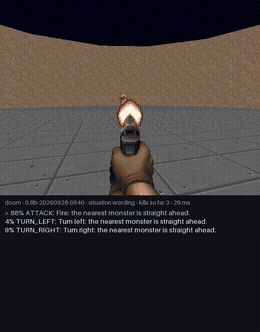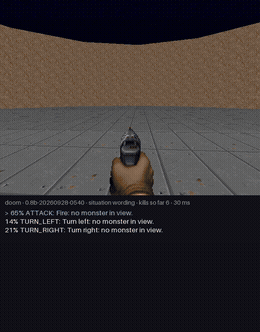
Jeff is a 0.8B open model that does one thing: it picks between options. You describe a situation, list the choices in plain words, and it returns a calibrated probability for each one from a single forward pass. It generates no text, so there's nothing to parse out of a chat reply. The idea is to let a big local model like Qwen3.8-27B do the writing and planning, and put Jeff in front of it for the small calls. Is this a prompt injection? Which tool should the agent call? Which team gets this ticket?
How it works
The base model is trained to choose between listed options and to report honest confidence. On top of it you load LoRA adapters, one per job. There are 15, including guard, triage, tools, ground, spam, legal-clauses, aml, sanctions and two for Jeff-Code. You name the adapter in each request. A request with no adapter goes to the plain base. All 15 loaded together take 2.09 GB of GPU memory.
v1.3 is "adapter-first." The prompt puts the instructions and options first and the changing input last, so the fixed part can be cached. The cost is weak zero-shot accuracy on long, unfamiliar option lists. If you plan to run it without an adapter, the README says to use v1.2.
The README reports these numbers. Across 8 adapters, Jeff plus an adapter averages 94.6% accuracy against 86.6% for the 27B alone. That's 0.25 s per decision versus 8.1 s on an M4 Max. Jeff-Code uses the same idea inside a coding agent. Jeff handles routine steps like reading a file or running a search, and decides when Qwen needs to think hard. The pass rate stays about the same (62.4% vs 62.8%) and each task takes 0.68x the time.
Try it
git clone https://github.com/firelex/jeff && cd jeff
uv sync --no-default-groups --extra lora          # add --extra cuda on NVIDIA GPUs, --extra mac on Apple silicon
uv run --no-default-groups hf download mstrasser/jeff-base --revision v1.3 --local-dir jeff-base-v1.3
for name in guard tools ground; do
  uv run --no-default-groups hf download mstrasser/jeff-adapter-$name --revision v1.3 --local-dir adapters/$name
done
JEFF_CHECKPOINT=jeff-base-v1.3 JEFF_ADAPTERS=adapters PORT=8765 \
  uv run --no-default-groups --extra lora jeff-serve       # add JEFF_BACKEND=mlx and --extra mac on Apple silicon
From Python, you then create a jeff.Client pointed at that port, name an adapter, and send choice_question or yes_no_question objects.
My take
The framing is right. A lot of agent steps are really classification dressed up as generation, and spending 8 seconds of a 27B model on each one is a waste. The README is also more honest than most. It publishes the test sets and calibration error. It shows that the 27B fallback only helps on one task. And it admits that total time across all Jeff-Code tasks drops only 14%, because in about 5% of tasks Jeff-Code keeps going 30+ minutes longer where Qwen alone gives up.
The limits are real too. It handles English text only, and it doesn't reason. jeff-serve answers one request at a time and returns HTTP 529 if another arrives, unless you set JEFF_QUEUE_MS. Adapters only work on the base version they were trained for. The sanctions and soc adapters are non-commercial. The training data isn't released, and the 27B comparison comes from one setup on one Mac.
If you run a local agent stack with routing, guarding or triage steps, this is worth an afternoon. If you have your own labeled data, the adapter kit is the part to look at.