 clovercoder
AV1 video, zero frames back
digital-human-koubo feeds ffmpeg frames to `personmask <W> <H> [person|subject|auto]`, gets one mask per frame. The comment says why ffmpeg decodes: AVAssetReader silently gives 0 frames on AV1 on M1/M2 and misaligns on VFR.
andyhuo520/digital-human-koubo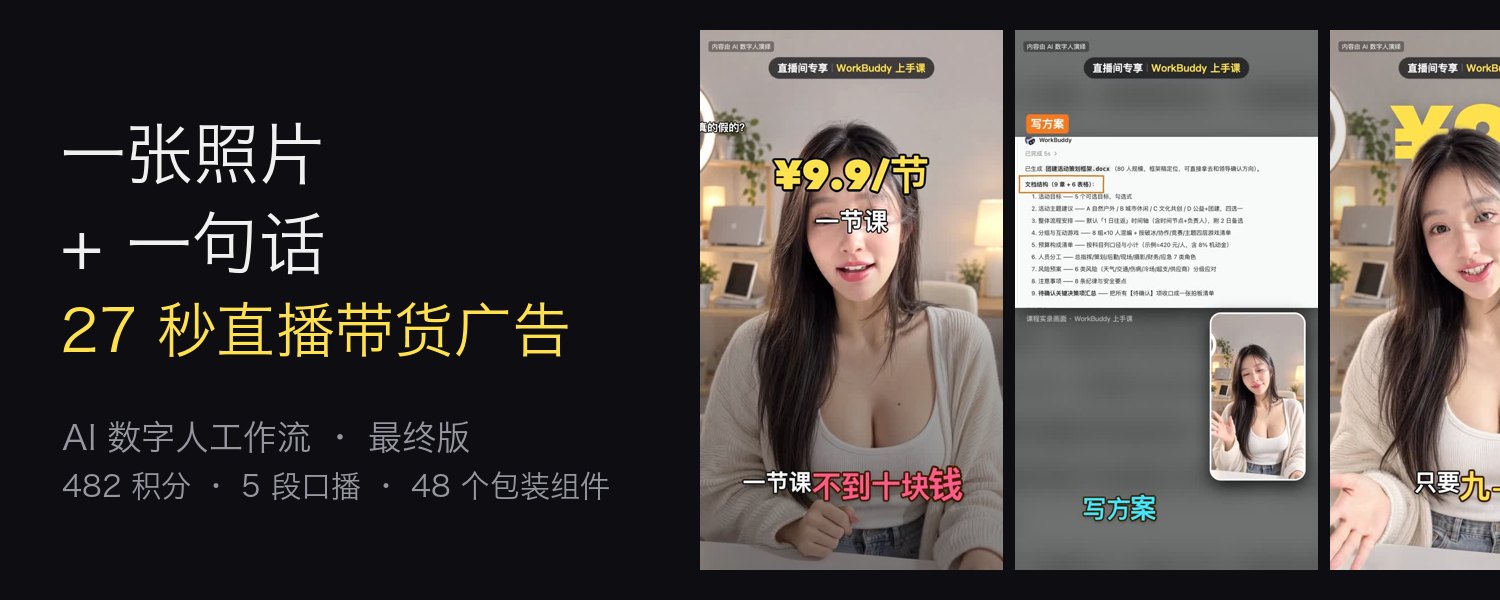
Digital Human Koubo is an agent skill that turns one photo and one sentence into a finished talking-head video. The README's example is a 27-second livestream ad for a course, with a fully AI presenter, voice, studio, captions and price animation. It says the only input was a one-line prompt and the cost was 482 Renoise credits. The problem it targets is the long chain between a script and a publishable video: generating clips, checking them, fixing the audio, editing and packaging.
How it works
The repo is a SKILL.md plus Python, shell and Remotion scripts. Your agent runs the pipeline in order.
It diagnoses your content, recommends 2 of 5 editing styles, and writes a script split into segments of 15 seconds or less. It then quotes the credit cost and waits for a "yes". Segment 1 is generated first so you can check it before the rest are batched. Video comes from Grok Video 1.5 through the Renoise MCP server.
Each segment is transcribed with whisper and compared with the script. Four frames per segment are inspected, because the README says Grok sometimes burns subtitles into the picture. Those segments get re-shot.
The part worth reading is scripts/voicefx/unify.py. Separately generated clips sound different, so the script matches each clip's spectrum to the median of the batch, capped at 4 dB per band. It then applies de-essing, adds one shared small-room reverb, and normalises to -18 LUFS. The README gives sibilance spread going from 13.2 dB to 5.9 dB in its own tests.
Editing happens in Remotion. A tl.json word-level timeline drives the timing, and 48 packaging components are layered on top. The README says these were measured frame by frame from 25 videos by named creators.
Try it
git clone https://github.com/andyhuo520/digital-human-koubo.git
cd digital-human-koubo
mkdir -p ~/.claude/skills && cp -R skills/digital-human-koubo skills/finance-explainer ~/.claude/skills/
/plugin marketplace add ArcoCodes/renoise-plugins-official
/plugin install renoise@renoise-plugins-official
bash ~/.claude/skills/digital-human-koubo/scripts/doctor.sh
Those are the Claude Code steps. The /plugin lines run inside Claude Code, and doctor.sh checks for ffmpeg, Python, Node and whisper. You also need a Renoise account, which logs in through the browser.
Worth knowing
- The README marks Claude Code as tested. Codex is "expected to work". OpenClaw and WorkBuddy are "should work".
- Full use needs skill loading, a remote MCP connection and local commands. Claude desktop and claude.ai are sandbox only, so local editing needs a shell agent.
- Generation spends Renoise credits. The agent quotes the cost before it generates.
- The text-behind-presenter effect uses Apple Vision and needs macOS.
- Swapping in a different voice, such as the optional Xiaomi MiMo TTS, leaves about 100 ms of lip offset, according to the README. It says this is visible in full-screen close-ups.
- The README says the languages it tested were English, Japanese, Korean, French, Spanish and Arabic, with whisper back-check scores of 94 to 100 percent.
- Many of the docs and code comments are in Chinese.
This suits developers already making short-form video with an agent who are willing to pay per clip. If you want a single prompt-to-video tool with no accounts or local setup, this is not it.