 clovercoder
DeepSeek Opens Its Production Inference Engine
DeepSeek open-sourced the inference engine behind their production services. Runs V4.1-Flash, offline only for now.
deepseek-ai/DeepInfer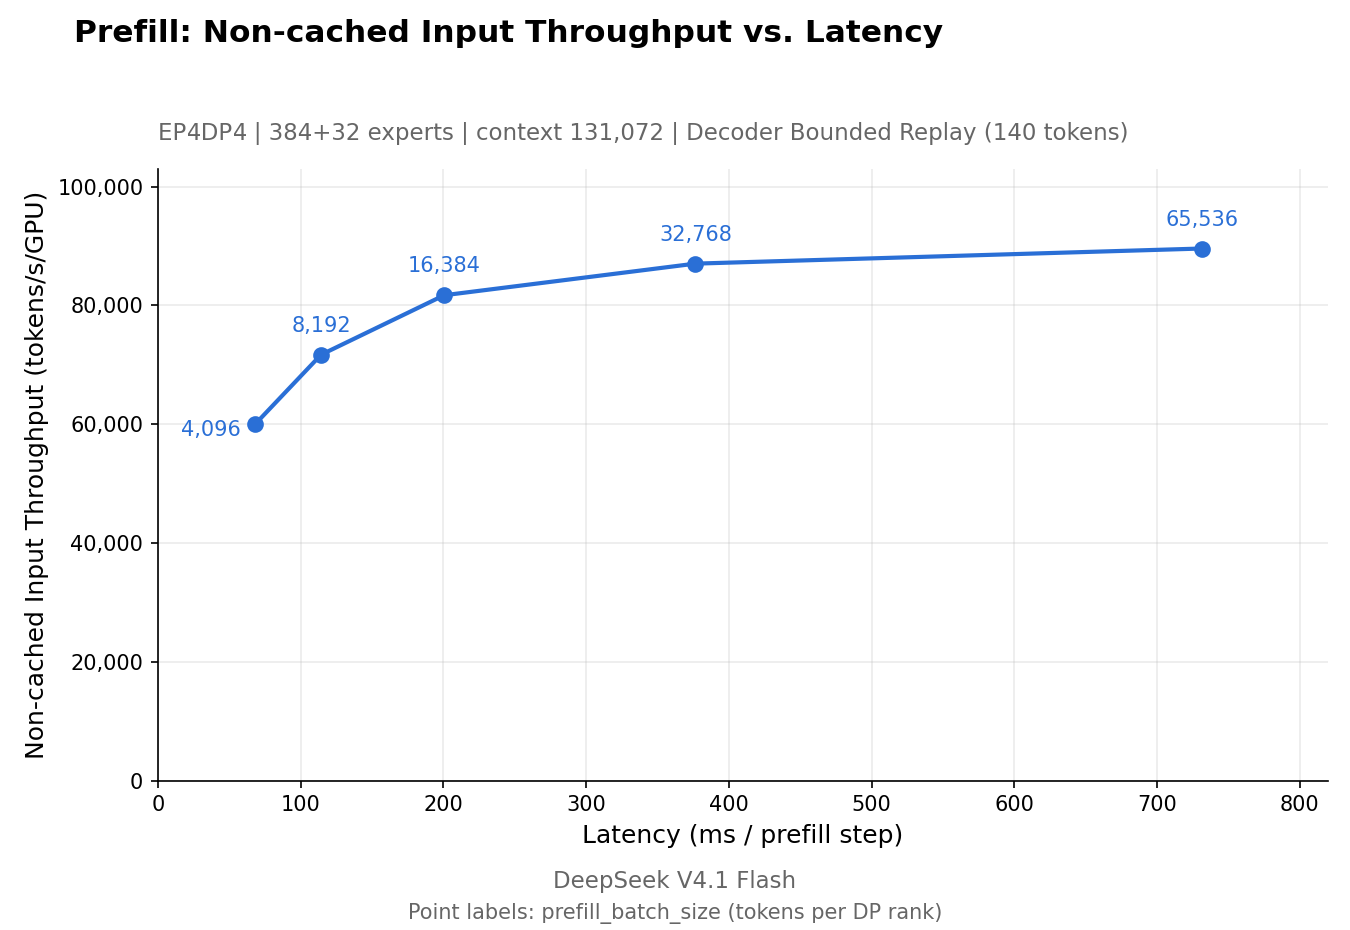
DeepInfer is DeepSeek's own inference framework for its models, and this open-source release covers offline inference. The README lists one supported model so far, DeepSeek-V4.1-Flash. If you've tried to run a large MoE model efficiently, you know the hard parts are the kernels, how you split the work across GPUs, and decode latency. DeepInfer is DeepSeek's answer to all three, from the people who trained the model.
How it works
The fast paths come from DeepSeek's own kernel libraries: FlashMLA, DeepGEMM, DeepEP, TileKernels and DeepSelect, plus custom TileLang kernels. The README says the framework started out built mainly on vLLM and borrows ideas from SGLang and TensorRT-LLM. So the structure will look familiar.
For parallelism it combines attention data parallelism, balanced context parallelism and MoE expert parallelism with EPLB. CPU batch scheduling runs alongside device execution, and that's on by default.
Two features stood out to me. DSpark is draft-token decoding where confidence decides when drafts get verified. Decoder SWA bounded replay cuts prefill work by replaying only a bounded suffix of the context. Both are opt-in through environment variables.
It also covers the things you need in production. You get structured outputs from regex, JSON schema or EBNF grammars. Batch-invariant inference and deterministic sampling with a fixed seq_seed are there too, but only on NVIDIA.
Try it
You need Linux, GCC 13+, Python 3.12, and CUDA 13 or CANN 9.2. Start from an empty Python 3.12 environment:
# Use `ascend` instead for the Ascend platform
# Keep it exported in the environment where you run DeepInfer
export DEEPINFER_ACCELERATOR=nvidia
./build.sh

python examples/offline_inference.py
On first run the default checkpoint deepseek-ai/DeepSeek-V4.1-Flash-1017 downloads to your Hugging Face cache, or you can set DEEPINFER_HF_MODEL_DIR to point at a local copy.
My take
The strength is obvious. This is the model vendor showing you how they think their model should run, and the kernels are real work. The repo includes throughput-versus-latency charts for prefill and decode and a script to rerun the sweep (examples/sweep/run_sweep.sh). I like that you can check the numbers yourself.
The limits matter just as much. Supported hardware is NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs, which leaves out most of us. The benchmarks used 4 GPUs for prefill and 64 for decode. The README also says plainly that this isn't a complete serving stack yet: there's no KV cache system, no prefill/decode disaggregation, and no load balancing across data-parallel replicas.
If you run DeepSeek models at scale on Blackwell-class or Ascend hardware, or you build inference engines, read this code. If you just want an endpoint on a single GPU, stay with vLLM or SGLang for now.